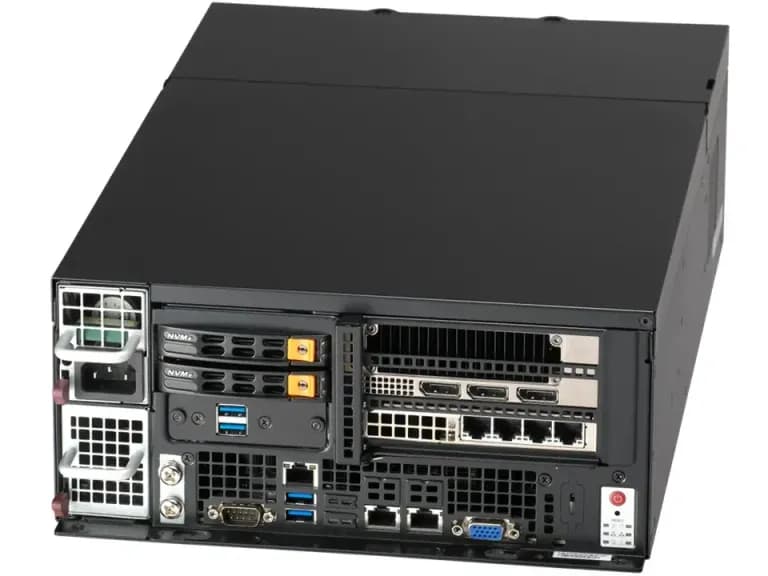
Supermicro SYS-E403-14B-FRN2T
SYS-E403-14B-FRN2T
144C Xeon / 2TB DDR5 / full-height GPU
Solution Blueprints
Serving a model at the site that uses it, because the round trip is too slow or the data is not allowed to leave.
There are two honest reasons to put inference at the site rather than in a datacentre, and neither of them is preference. Either the round trip is too slow for what the model is controlling, or the data is not permitted to leave the premises. Both are constraints, and neither is solved by a faster link.
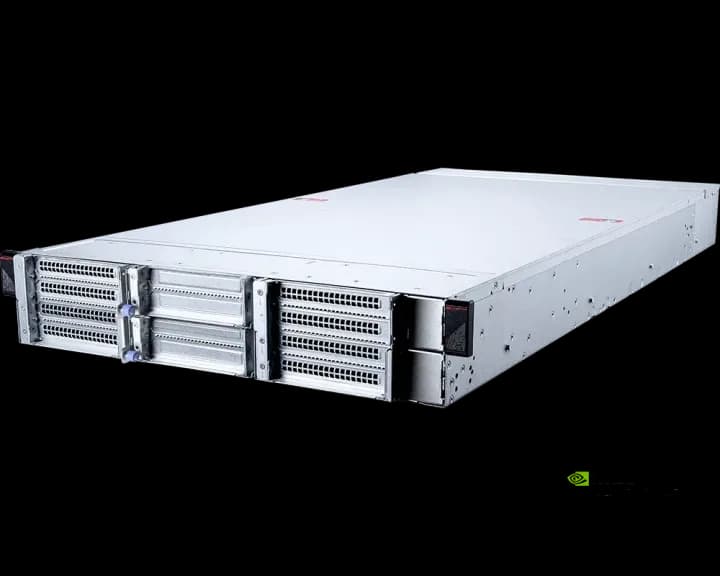
Where there is no rack and the toolchain needs x86, the E403 is the machine. It takes a full-height GPU and up to 2TB of DDR5 on a single Xeon reaching 144 cores, in a chassis 117mm tall weighing 8kg. That fits on a shelf in a plant room or a back office, which is where this class of deployment usually has to live.
Where the model is the constraint rather than the toolchain, the GB10 machines carry 128GB of coherent unified memory and up to 1 PFLOP of FP4 in a chassis of about the same size. The EdgeXpert is positioned for exactly this, at 240W. The caveat is the same one that applies in the lab: GB10 is Arm, so anything shipping as an x86 binary needs confirming before the order rather than after.
Where a rack does exist at the site, the CG290 is the step up: single-socket 2U taking up to four accelerators, which serves a real workload without asking the site for datacentre power. And where the site has no fibre, the Starlink terminal is the link that makes any of this reportable back to head office. That pairing is covered in more depth in the blueprint for remote sites.
Inference runs where the data is generated, which is the only design that satisfies a residency requirement rather than working around one.
A 117mm, 8kg chassis on a shelf in a plant room, rather than a facility project to house one server.
Where a rack exists, a single-socket 2U takes four accelerators without asking the site for datacentre power.
SYS-E403-14B-FRN2T
144C Xeon / 2TB DDR5 / full-height GPU
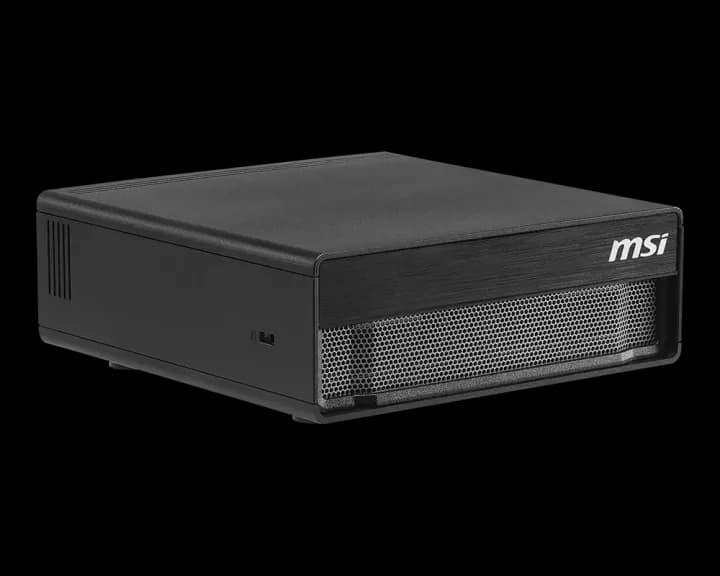
MS-C931
128GB LPDDR5X / 1 PFLOP FP4 / Edge ready
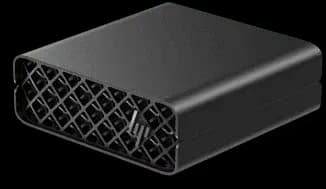
ZGX Nano G1n
GB10 Superchip / 128GB unified / 150mm chassis
S3063G290RAU4
4x PCIe accelerators / 2U / single socket
ST-PERFORMANCE
140 degree FOV / IP69K / 270 kph survivable
Tell us the workload and the power envelope you have to work within. We will come back with a configuration, a lead time and a written quote.